Mistral Large 4: What It Is and Who Should Use It
Mistral Large 4 is a 1 trillion parameter open-weight model with real strength in security work. Specs, benchmarks, price, and who should try it now.
Mistral Large 4 is the first open model in a year that a security team should drop everything to test.
Everyone else can wait three weeks.
Mistral released Mistral Large 4 on October 6, 2026, as a public preview API. It is a 1 trillion parameter mixture of experts model with 49 billion parameters active per token, it reads text and images, and it costs $1.36 per million input tokens and $4.18 per million output tokens (Mistral). The weights, the part that makes it "open," are not out yet. Mistral says they ship by the end of October.
That's the answer in three sentences.
The part that matters is where it wins and where it doesn't. It is not the smartest model you can rent today. Not close. It is, by the numbers Mistral published and an independent lab confirmed, one of the best models in the world at defensive security work, partly because it does the jobs closed models refuse to touch.
Mistral Large 4 is a specialist dressed as a generalist, and you should judge it like one.
Here's what it is, what the benchmarks say, what it costs, how it stacks up against the models you already use, and who should try it this week.
Mistral Large 4 in one table
Mistral nicknamed the model "Le Chonk," which tells you how seriously they take the naming and how seriously they take the size. Under the joke, the spec sheet is plain enough to put in one place.
These are the numbers that matter, pulled from Mistral's announcement, its model docs and the independent benchmark pages that went live the same day.
| Spec | Mistral Large 4 |
|---|---|
| Released | October 6, 2026 (public preview) |
| Total parameters | About 1.05 trillion |
| Active per token | 49 billion |
| Architecture | Mixture of experts, hybrid instruct and reasoning |
| Input | Text and images (up to 100 images per request) |
| Output | Text |
| Context window | 1M tokens per Mistral's docs; 512K as served in preview, per Artificial Analysis and Vals |
| Max output | 256K tokens (per Vals) |
| API price | $1.36 in / $4.18 out per 1M tokens |
| Cached input | $0.14 per 1M tokens |
| Launch discount | 50% off for the first two weeks |
| Weights | Due end of October 2026 (October 27, per The Next Web) |
| License | Not yet announced |
| Languages | Trained on 160+ languages |
Two lines in that table deserve a second look.
The context window is the first. Mistral's documentation describes a 1 million token window, but Artificial Analysis lists 512K tokens for the preview, and Vals lists the same.
The likely reading is that the architecture supports 1M and the preview endpoint serves half of it. If your work depends on stuffing a whole codebase or a year of contracts into one prompt, test the limit yourself before you build on it.
The license is the second. "Open weights" with no license yet is a promise, not a permission. Until Mistral publishes the terms, you don't know whether you can ship a commercial product on a self hosted copy.
The other number worth understanding is the 49 billion active parameters. A mixture of experts model only wakes up a slice of itself for each token, roughly 4.7% of the weights here. That's why a trillion parameter model can be priced like a mid tier one.
It's also why "1 trillion" is a misleading number if you plan to run it yourself. The full model still has to sit in memory, so the hardware bill is set by the trillion, and the speed is set by the 49 billion.
What Mistral Large 4 does better than anything open
Mistral spread its launch across a lot of categories. Cybersecurity is the one where the numbers are the strongest, and it's the one where the argument is the most interesting.
On the Artificial Analysis Cyber Index, an independent score of how well models find and fix real security flaws, Mistral Large 4 Preview scores 50. That puts it level with GLM-5.3-Flash and behind MiMo-V2.6-Pro at 56, and Artificial Analysis expects it to land in the top three open weights models on that index once the weights ship.
The single test inside that index where it leads is CyberGym-E2E. The task: reproduce a real vulnerability in open source software, then patch it. Mistral Large 4 scores 82%. MiMo-V2.6-Pro scores 79%. GPT-6 Luna at max reasoning scores 78%.
On Cybench, a set of 40 exercises drawn from security competitions, Mistral reports 93%.
Here's the line from the announcement that should get a security lead's attention. Mistral says several leading closed models, naming Claude Opus 5.5 and GPT-6 Astra, "score near zero on the same test because they refuse to perform the task" (Mistral).
That is a strong claim from the company selling the alternative, so read it with that in mind. But the logic holds up.
Defending software often starts with proving a flaw is real. You reproduce the bug, you watch it break, then you fix it. A closed model's safety filter can't always tell the defender reproducing a bug from the attacker weaponizing one, so it refuses both. If your job is incident response at 2 a.m., a model that says no is a model you can't use.
Mistral's answer has two halves. The first is capability: a model that does the defensive work. The second is control: open weights you can run on your own hardware, under your own policy, where nobody can switch off a capability in the middle of an incident.
You might be thinking: a model that does vulnerability work without refusing sounds like a gift to attackers.
Fair. Mistral addresses it directly, and the numbers are worth knowing. On cyber prompts drawn from JailbreakBench, StrongREJECT and AgentHarm, Mistral says Mistral Large 4's average refusal rate on malicious requests is higher than every open model it compared against.
On Lakera's B3 agent security benchmark, it resists 93.3% of attacks. Until the weights ship, Mistral is red teaming the model with security firms and state authorities.
So the claim is narrower than "it does anything you ask." It's "it does the defensive work closed models refuse, and still refuses the obviously malicious request more often than its open peers." Whether that line holds once anyone can download the weights is the question nobody can answer until October 27.
Where it is strong outside security
Cyber is the headline. It's not the only place Mistral Large 4 has a real result, and a few of the others matter more to ordinary work.
Coding first. Mistral reports 61.7% on DeepSWE v1.1, 59.4% on SWE-Atlas-QnA and 28.3% on Terminal-Bench 4, for a combined Coding Agent Index score of 49.8%, which it says is ahead of DeepSeek V4 Pro 0813 and Qwen3.8 Max.
Mistral notes those numbers come from the Artificial Analysis harness and were run privately before that harness went public, so you can't reproduce them yet.
The more honest coding signal is a blind human test. Mistral ran it with Surge AI: professional annotators scored outputs from five models on a 1 to 5 scale without knowing which was which. Mistral Large 4 scored 3.74, second of five. Kimi K3 scored 3.59 and GLM-5.3 scored 3.60. Claude Opus 5 scored 4.22.
Read that last number twice. In Mistral's own test, the best open coder it could find still lost to the previous generation of Claude by half a point on a five point scale.
Knowledge work is the second area. Mistral had Vals run legal and finance tasks, and says the model beat GPT-6 Astra on both. Vals' own page puts its best result at sixth of 75 on Harvey's Legal Agent Benchmark. On AutomationBench, 657 business workflows across Gmail, Google Sheets, Slack and Salesforce, Mistral reports 59.9%.
Images are the third, and this is the result that stands out most on paper.
Mistral says Mistral Large 4 beats GPT-6 Astra on Dense 200, a visual grounding test, 42% to 41%. Visual grounding means pointing at the exact thing in a picture: this bolt, that crack, the third car from the left. The launch demos lean hard on it, with engineering drawings checked part by part and huge satellite images searched for small objects.
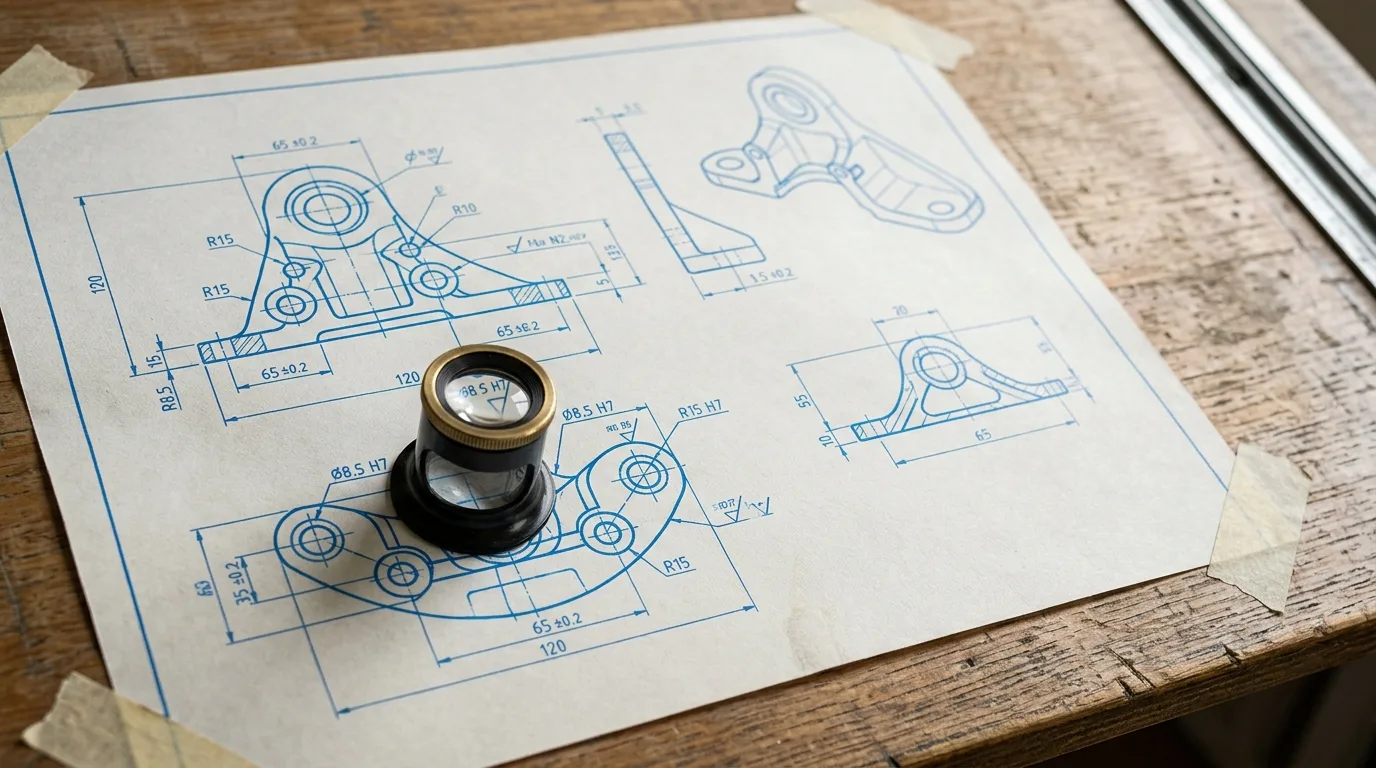
The API change behind it is small and practical. Mistral's API now takes 100 images per request, up from 8 for its earlier models, according to Artificial Analysis. On GDP.pdf, a document and image reasoning test, the model scores 19%, an 18 point jump over Mistral Large 3. If you inspect drawings or site photos in batches, that limit was the thing in your way, and it's gone.
How Mistral Large 4 compares to the models you already use
This is where expectations need setting, because "1 trillion parameters" sounds like a frontier model and the scores say otherwise.
Artificial Analysis gives Mistral Large 4 Preview a 38 on its Intelligence Index, a composite of reasoning, knowledge and coding tests. GPT-6 Luna at max reasoning also scores 38. DeepSeek V4.1 Flash at max scores 39. Gemini 4 Argon, which Google announced on September 30, ties GPT-6 Astra at the top of the same index.
Put plainly: Mistral Large 4 is a strong model in the middle of the pack, not a rival to the frontier. Artificial Analysis frames it as the most intelligent model built outside the US and China, which is true and also tells you where the bar sits.
This table lines it up against its closest open rivals, using the figures published at launch.
| Model | Total / active params | Context | Image input | API price (in / out per 1M) | Weights |
|---|---|---|---|---|---|
| Mistral Large 4 | 1.05T / 49B | 512K served, 1M documented | Yes | $1.36 / $4.18 | Due end of October |
| DeepSeek V4 Pro | 1.6T / 49B | 1M | No | Varies by provider | Available, MIT |
| Kimi K3 | 2.8T / ~104B | 1M | Yes | $3.00 / $15.00 | Available, modified MIT |
| GLM-5.3 | Not published | 1M | No | $1.40 / $4.40 | Available |
The open rival comparison comes from MarkTechPost's launch coverage, which collected the published specs for each.
Against closed frontier models the gap is wider. Vals ranks Mistral Large 4 32nd of 44 on its own index at 48.05%. If the only question you ask is "which model is smartest," the answer is a closed one from Google, OpenAI or Anthropic, and this post would be short.
For a fuller picture of how the frontier sits right now, our breakdown of Gemini 4 Argon covers the model at the top.
There's a second catch, and it's about cost per task.
Per token, Mistral Large 4 looks cheap. Per finished job, it isn't. Artificial Analysis measured $1.13 per Intelligence Index task at list price, and $0.57 with the two week launch discount. GLM-5.3-Flash costs $0.25 per task and DeepSeek V4.1 Flash costs $0.27. That's more than four times the cost per task of open models with similar scores.
The reason is usually tokens. A model that thinks out loud for longer burns more output tokens to reach the same answer, and output is the expensive side of the bill. If you've only ever compared models by the price per million tokens on the pricing page, this is the number that changes your mind.
The three people who should try Mistral Large 4 now
Most people should not switch to this model. A few should test it this week, and they're easy to name.
Use this to find yourself.
| If you are | Try it now? | Why |
|---|---|---|
| A security team doing vulnerability research or incident response | Yes | It does defensive work closed models refuse, and you'll be able to run it in house |
| A company that needs EU data residency or self hosting | Yes, and plan for the weights | Trained and served in Mistral's own European datacenters, with weights coming |
| A team inspecting drawings, documents or photos in volume | Yes | 100 images per request and strong visual grounding |
| A developer choosing a daily coding model | Not yet | Closed models still lead the blind tests |
| Anyone who wants the smartest general model | No | It scores mid pack on independent intelligence indexes |
| Anyone on a tight per task budget | Wait for the discount to end and compare | Cost per task runs 4x similar open models |
Start with the security team, because that's who the launch is built for.
If your models refuse when you ask them to reproduce a bug, Mistral Large 4 is the first open model with published evidence that it won't, and with a plan to put the weights on your hardware.
Test it on the work you actually do: pick three vulnerabilities your team handled this quarter, rerun the reproduction step with the preview API, and count how many it completes without a refusal and without a wrong exploit. That's a better test than any public benchmark, and it takes an afternoon.
The second person is whoever answers to a European regulator. Mistral trained the model on 3,800 NVIDIA Grace Blackwell GPUs in its own datacenters in Europe and serves the preview there. It also says it will run a European deployment end to end, under European law, independent of other digital service providers (Mistral).
If "where does the data go" is the first question in your procurement review, that sentence is the answer you've been waiting for from a lab of this size.
The third is anyone whose work is mostly pictures of things. Insurers looking at storm damage in aerial photos, utilities checking power lines, engineers verifying parts against drawings. The Next Web reports that Mistral is aiming the model at exactly these jobs, including turning technical drawings into CAD models. Send it a batch of 100 real images from last month and check its answers against what your team already decided.
Now the person who should wait: the developer looking for a new daily coding partner.
It's tempting, because the agentic coding scores look strong and the price per token is low. But the blind test is the one that predicts your day, and in it Claude Opus 5 beat Mistral Large 4 by half a point.
Add the higher cost per finished task and the reproducibility caveat on the coding numbers, and the switch costs you more than it saves. If you write code all day, run one real ticket through it for curiosity, then go back to what works. Revisit when the weights land and independent coding results come in.
Everyone else has a simple rule: keep using what works, and revisit after October 27.
What happens when the weights drop
The open part of this model doesn't exist yet. That's worth sitting with.
Right now, Mistral Large 4 is a closed preview API that happens to come with a promise. You send prompts to Mistral's servers and pay per token, the same as you would with any closed model. Everything that makes it special for security and sovereignty depends on a download that hasn't happened.
Mistral has committed to more with the weights release: the weights themselves, more detail on the architecture, and more benchmarks and post training notes. The expert count and routing details are still unpublished, so nobody outside Mistral can yet tell you exactly how much memory a self hosted copy needs.
These are the things that will decide whether the open release lives up to the launch.
- The license. A permissive license like DeepSeek's MIT means you can build a product on it tomorrow. A restrictive one means legal review before anything ships.
- The hardware bill. A trillion parameters has to live somewhere. Even with aggressive compression, this is a multi GPU server model, not a laptop model. Price the hardware before you plan the migration.
- The safety behavior, unfiltered. The API preview runs behind Mistral's own moderation. Downloaded weights run behind whatever you put in front of them. Watch for independent tests once anyone can probe it directly.
- Whether the downloaded model matches the preview. A weights release that lands weaker than the API you tested is a surprise you want to catch on day one.
There's also the model's trajectory. Mistral says the reinforcement learning run behind this preview "is still in flight" and showing no signs of saturation, and that it expects large, rapid improvements in the coming weeks (Mistral).
Take that as a roadmap, not a result. But it means the scores in this post are a snapshot of a model that's still moving, and the version you download in late October may not be the one tested on October 6.
If you plan to self host, do the boring prep now. Find out which servers you'd run it on. Write the test prompts you'll use to compare the downloaded model against the API preview. Put the license on your legal team's calendar for the week of October 27. When the weights land, you'll be testing in an hour instead of starting a project.
Why Mistral Large 4 matters even if you never use it
You can ignore this model and lose nothing today. You can't ignore what it says about where open models are going.
A year ago, the open models that kept up with the closed ones came almost entirely from Chinese labs. Mistral's own Large 3 was, by most accounts, a disappointment. Mistral Large 4 puts a European lab back near the top of the open rankings, funded by a €3 billion round that Mistral calls the largest equity raise ever by a European tech company.
That matters for one practical reason. More good open models from more countries means more choices for anyone who can't, or won't, send their data to a US or Chinese provider. More choices mean more bargaining power, even if you never switch.
The second reason is the refusal argument. Mistral built its launch around a real weakness of closed models: a safety filter can make a model useless for a legitimate job. That argument will keep coming up in security, medicine and law, and every closed lab will have to answer it.
And the last reason is the lesson for your own work.
The best model is the one that does your job, not the one at the top of a leaderboard. A security team will get more from a mid pack model that does vulnerability work than from a smarter model that refuses it. Your writing model and your coding model probably shouldn't be the same model either, and the best one for each job will change every few months.
That's the case for not marrying a single provider. If you want the plain explanation of how a single workspace with many models works, we wrote it up in what an AI aggregator actually is.
You'll find every model release we cover, and the comparisons that go with them, in the artificial intelligence section of the blog.
How to try Mistral Large 4 this week
Here's the shortest path from reading about it to knowing whether it's for you.
The preview runs through Mistral Studio, Mistral's developer console, and the model docs cover the endpoints. The preview API supports function calling, structured outputs, document Q&A, batching, and Mistral's Agents and Conversations endpoints. So if you already have code that calls another provider's API, the move is mostly a model name and an endpoint change.
Follow these steps in order.
- Get access through Mistral Studio and confirm the model name in the docs before you write any code. Preview names change.
- Pick one real job, not a demo. A vulnerability you already fixed. A contract you already reviewed. A folder of 50 site photos your team already labeled.
- Run the same job on the model you use today, with the same prompt.
- Score both on the thing you care about: did it finish, was it right, and how long did your team spend fixing it.
- Write down the cost per finished job, not the price per token. Do it during the 50% discount and again after, because the discount ends two weeks from launch.
- Test the context window with your largest real input. If it fails above 512K tokens, you've found the preview's limit.
Two runs on your own work will tell you more than every chart in this post.
If you'd rather compare models side by side without wiring up another API key, that's the job Magai does: one workspace where you can switch models mid conversation and keep the whole thread, so the second model sees exactly what the first one saw. We haven't announced Mistral Large 4 in Magai, so check the model picker before you plan around it.
For moving a single task across several models without losing context, our guide to switching AI models in one workflow walks through it.
So which job do you have that a smarter model keeps refusing?
Test that one first. Then decide.
More in Artificial Intelligence
Artificial Intelligence
Grok vs ChatGPT: The Switching Cost Nobody Prices
Benchmarks say Grok and ChatGPT are close. The real difference shows up the moment you switch between them mid-task, and it costs you every time.
Artificial Intelligence
MCP Servers: Which Ones Are Worth Connecting
There are thousands of MCP servers now, and most aren't worth the risk. Here's how to tell the few worth connecting from the rest.
Artificial Intelligence
Gemini vs ChatGPT: What Actually Decides It
Gemini and ChatGPT cost almost the same now and do almost the same things. Here's the one difference that actually decides which gets your card number.